> ## Documentation Index
> Fetch the complete documentation index at: https://docs.comfy.org/llms.txt
> Use this file to discover all available pages before exploring further.
# Ming Image 0.1 Design: RGBA Text to Image in ComfyUI
> Generate design layouts with legible text and transparent backgrounds using Ming Image 0.1 Design, a 6B open-weights model from inclusionAI in ComfyUI
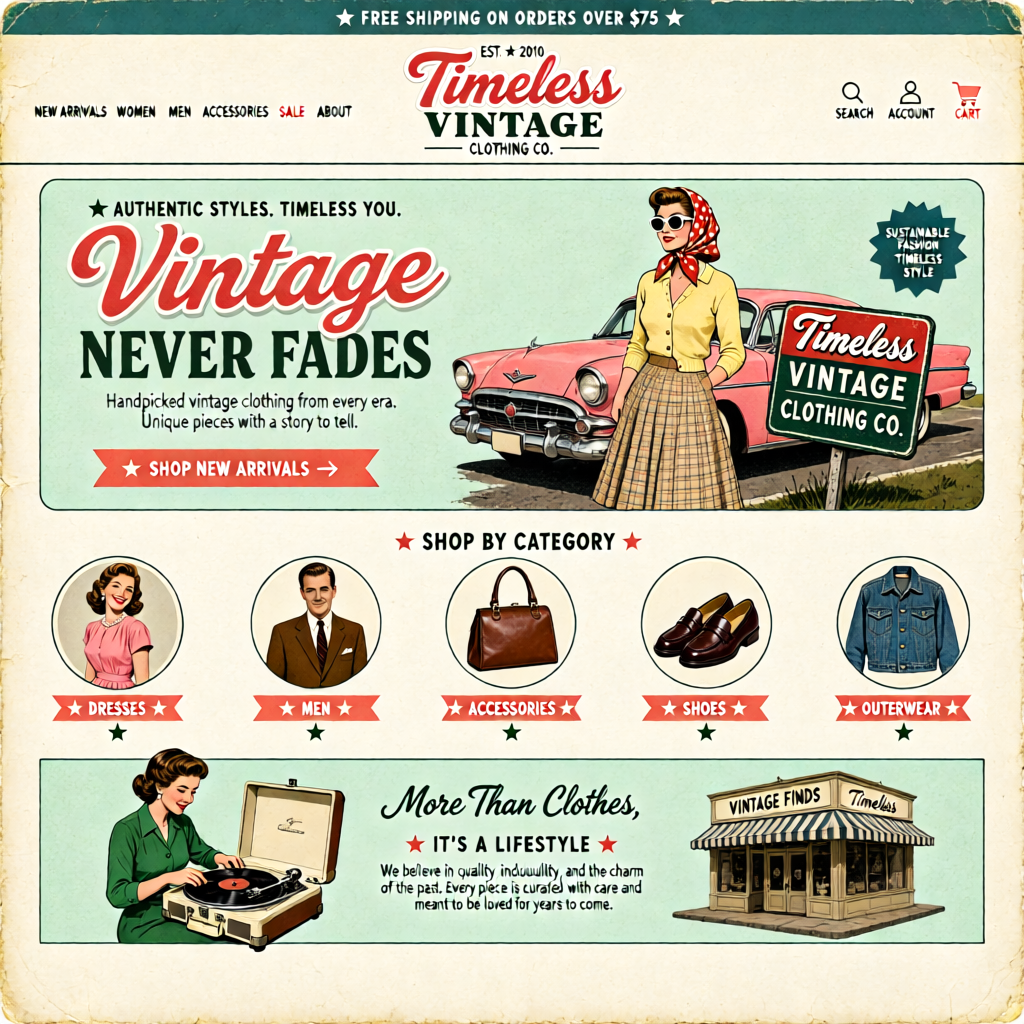
**Ming Image 0.1 Design** is a 6B open-weights text-to-image model from inclusionAI (Ant Group), released under the MIT license. It targets design work rather than photographic realism: UI screens, infographics, posters, and other layouts that carry a lot of text. Outputs are RGBA with a real alpha channel, so a transparent result can be dropped straight into a design file.
The workflow puts a prompt-rewriting stage in front of the sampler. Qwen3.8-27B expands a short idea into a structured layout caption before sampling, and the enhancer can be switched off when you want your text sent exactly as typed.
**Related links**
* [inclusionAI/Ming-Image (GitHub)](https://github.com/inclusionAI/Ming-Image)
* [Comfy-Org/Ming-Image (Hugging Face)](https://huggingface.co/Comfy-Org/Ming-Image)
* [inclusionAI/Ming-Image-0.1-Design (Hugging Face)](https://huggingface.co/inclusionAI/Ming-Image-0.1-Design)
## What Ming Image 0.1 Design is good at
* **Long, structured layouts**: pages, posters, and infographics with many sections, composed section by section
* **Text rendering**: strings quoted in the prompt are followed closely, so labels, prices, and headings stay legible
* **Transparent output**: RGBA images with a real alpha channel for compositing isolated elements
* **Prompt rewriting**: an instruction-following vision language model expands a short brief into a detailed layout caption
* **Open weights**: MIT licensed, so the checkpoints can be used and fine-tuned freely
## Example outputs
Text-to-image generation of a text-heavy layout, saved as a single PNG:
Make sure your ComfyUI is updated.
* [Download ComfyUI](https://www.comfy.org/download)
* [Update Guide](/installation/update_comfyui)
Workflows in this guide can be found in the [Workflow Templates](/interface/features/template).
If you can't find them in the template, your ComfyUI may be outdated.
If nodes are missing when loading a workflow, possible reasons:
1. You are not using the latest ComfyUI version (Nightly version)
2. Some nodes failed to import at startup
* [Cloud](https://cloud.comfy.org) will update after ComfyUI stable release.
So, if you find any core node missing in this document, it might be because the new core nodes have not yet been released in the latest stable version. Please wait for the next stable release.
## Ming Image 0.1 Design text-to-image workflow
Generate a design composition from a text prompt, with the model handling layout, typography, and background transparency.
 Download JSON or search "Ming Image 0.1 Design" in Template Library
### Steps to run the workflow
1. Enter the **Text to Image (Ming Image 0.1 Design)** subgraph with the **Enter subgraph** button at the bottom of that node
2. Write your prompt in the `prompt` field, describing the layout section by section and putting any copy you want rendered inside quotes
3. Choose the canvas with the `ResolutionSelector` node: 2048 x 2048 gives the best quality, 1024 x 1024 is faster
4. Leave the prompt enhancer on to let Qwen3.8-27B expand your prompt, or switch `enable_PE` off to send your text exactly as typed
5. Queue the prompt. The decoded image appears in the `PreviewImage` node
6. For a transparent background, prepend one RGBA phrase to your prompt, for example `RGBA, 4-channel, transparent background`
### Model downloads
Diffusion model for Ming Image 0.1 Design (loaded by the template).
Text encoder for Ming Image 0.1 Design (loaded by the template).
Prompt-rewriting text encoder used by the prompt enhancer.
VAE for Ming Image 0.1 Design.
**Model Storage Location**
```
📂 ComfyUI/
├── 📂 models/
│ ├── 📂 diffusion_models/
│ │ └── ming_image_0.1_design_int8_convrot.safetensors
│ ├── 📂 text_encoders/
│ │ ├── ming_image_0.1_ling_mini_2.0_int8_convrot.safetensors
│ │ └── qwen3.8_27b_w4a8.safetensors
│ └── 📂 vae/
│ └── ming_image_vae_bf16.safetensors
```
The same repository also publishes full-precision checkpoints, [ming\_image\_0.1\_design\_bf16.safetensors](https://huggingface.co/Comfy-Org/Ming-Image/resolve/main/diffusion_models/ming_image_0.1_design_bf16.safetensors) and [ming\_image\_0.1\_ling\_mini\_2.0\_bf16.safetensors](https://huggingface.co/Comfy-Org/Ming-Image/resolve/main/text_encoders/ming_image_0.1_ling_mini_2.0_bf16.safetensors), plus `_layer` variants of both the diffusion model and the text encoder.
## Prompt guide
* [Text-to-image prompt rewriting](https://github.com/inclusionAI/Ming-Image#text-to-image-prompt-rewriting): the official prompt structure and the rewriter system prompt that this workflow's enhancer runs
* [Transparent-background generation tip](https://github.com/inclusionAI/Ming-Image#transparent-background-generation-tip): the fixed RGBA phrases to prepend to a prompt
## Get started
1. Update ComfyUI to the latest version. Ming Image 0.1 support is in the newest ComfyUI builds
2. Go to Template Library, search for `Ming Image 0.1 Design`
Comfy Desktop and Comfy Cloud follow stable releases, so a model that is only supported in the newest ComfyUI build may not be available there yet.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.