> ## Documentation Index
> Fetch the complete documentation index at: https://docs.comfy.org/llms.txt
> Use this file to discover all available pages before exploring further.
# PiD Latent Upscale ComfyUI Workflow Example
> PiD (Pixel Diffusion Decoder) turns a diffusion latent into a 4x super-resolved image in 4 distilled pixel-space steps. No separate VAE decode needed.
**PiD (Pixel Diffusion Decoder)** turns a diffusion **latent** into a **4x super-resolved image** in 4 distilled pixel-space steps. No separate VAE decode needed. This workflow demonstrates using PiD to upscale a Z-Image-Turbo latent from **1024px to 4096px**.
**Related Links**:
* [Comfy-Org/PixelDiT on Hugging Face](https://huggingface.co/Comfy-Org/PixelDiT)
* [nvidia/PixelDiT-1300M-1024px (official release)](https://huggingface.co/nvidia/PixelDiT-1300M-1024px)
 Make sure your ComfyUI is updated.
* [Download ComfyUI](https://www.comfy.org/download)
* [Update Guide](/installation/update_comfyui)
Workflows in this guide can be found in the [Workflow Templates](/interface/features/template).
If you can't find them in the template, your ComfyUI may be outdated.
If nodes are missing when loading a workflow, possible reasons:
1. You are not using the latest ComfyUI version (Nightly version)
2. Some nodes failed to import at startup
* [Cloud](https://cloud.comfy.org) will update after ComfyUI stable release.
So, if you find any core node missing in this document, it might be because the new core nodes have not yet been released in the latest stable version. Please wait for the next stable release.
Download JSON or search "Image Upscale: PiD Latent Decode" in Template Library
## How PiD works
PiD matches checkpoints by the **VAE / latent space** of the upstream model (the encoder side), not the diffusion model name alone. You need to select the PiD checkpoint that corresponds to the latent space of the model used for initial generation.
This workflow uses **Z-Image-Turbo** (1024px latent to 4096px output) which shares Flux.1's 16-ch VAE.
This workflow uses Subgraph nodes for modular processing. Check out the Subgraph documentation to learn how to customize and extend the workflow.
### Available PiD checkpoints
All checkpoints are downloaded from [Comfy-Org/PixelDiT](https://huggingface.co/Comfy-Org/PixelDiT) to `models/diffusion_models/`.
| Checkpoint | Input to Output | Compatible latent (VAE backbone) |
| - | - | - |
| [`pid_flux1_512_to_2048_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_flux1_512_to_2048_4step_bf16.safetensors) | 512 to 2048 | Flux1-dev 16-ch VAE (Flux.1, Z-Image) |
| [`pid_flux1_1024_to_4096_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_flux1_1024_to_4096_4step_bf16.safetensors) | 1024 to 4096 | Flux1-dev 16-ch VAE (Flux.1, Z-Image) **(this workflow)** |
| [`pid_flux2_512_to_2048_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_flux2_512_to_2048_4step_bf16.safetensors) | 512 to 2048 | Flux2-dev 128-ch VAE (Flux.2) |
| [`pid_flux2_1024_to_4096_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_flux2_1024_to_4096_4step_bf16.safetensors) | 1024 to 4096 | Flux2-dev 128-ch VAE (Flux.2) |
| [`pid_sd3_512_to_2048_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_sd3_512_to_2048_4step_bf16.safetensors) | 512 to 2048 | SD3 medium 16-ch VAE |
| [`pid_sd3_1024_to_4096_4step_bf16`](https://huggingface.co/Comfy-Org/PixelDiT/resolve/main/diffusion_models/pid_sd3_1024_to_4096_4step_bf16.safetensors) | 1024 to 4096 | SD3 medium 16-ch VAE |
### Subgraph settings
Configure these on the **Latent Upscale Decode (PiD)** subgraph:
| Setting | Value | Description |
| - | - | - |
| `latent_format` | `flux` | `flux` for Flux.1/Flux.2/Z-Image, `sd3` for SD3 (Flux.2 is auto-detected by 128 channels) |
| `degrade_sigma` | `0.0` | How "finished" the input latent is. `0.0` for fully denoised (default), `0.1–0.8` for partially denoised, `1.0` for pure noise |
### Steps to run
1. **Generate a latent**. Use a T2I workflow (e.g., Z-Image-Turbo) to produce a latent image.
2. **Connect to PiD**. Feed the latent into the **Latent Upscale Decode (PiD)** subgraph node.
3. **Select checkpoint**. Choose the PiD checkpoint matching your upstream model's VAE latent space.
4. **Set output size**. Set PiD output size to **4x** the input latent resolution.
5. **Run**. The subgraph decodes and upscales in a single 4-step pass.
## Model downloads
PiD is part of the PixelDiT model family. This workflow also requires the Z-Image-Turbo model for initial generation.
pid\_flux1\_1024\_to\_4096\_4step\_bf16.safetensors: PiD checkpoint for Flux.1 / Z-Image latent space
z\_image\_turbo\_bf16.safetensors: used for initial generation before PiD upscale
qwen\_3\_4b.safetensors: text encoder for Z-Image-Turbo
ae.safetensors: VAE for Z-Image-Turbo
gemma\_2\_2b\_it\_elm\_fp8\_scaled.safetensors: text encoder for PiD subgraph CLIPLoader (type: pixeldit)
> PiD uses a built-in **pixel\_space** VAE. No separate VAE file is needed for PiD itself.
### Model storage location
```
📂 ComfyUI/
├── 📂 models/
│ ├── 📂 text_encoders/
│ │ ├── qwen_3_4b.safetensors
│ │ └── gemma_2_2b_it_elm_fp8_scaled.safetensors
│ ├── 📂 diffusion_models/
│ │ ├── pid_flux1_1024_to_4096_4step_bf16.safetensors
│ │ └── z_image_turbo_bf16.safetensors
│ └── 📂 vae/
│ └── ae.safetensors
```
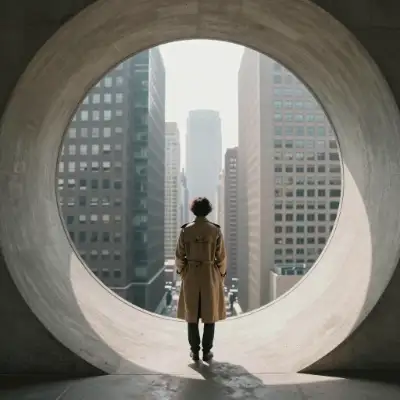
### Sample output
 This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.