- Visual understanding: Reads and analyzes image content through the Qwen2.5-VL foundation model
- Text-to-image generation: Creates high-fidelity images from text prompts
- Instruction-guided image editing: Applies complex edits from natural language instructions
- In-context generation: Combines people, reference objects, and scenes from multiple inputs into new images
- Dual-path architecture: 3B Qwen2.5-VL text model plus an independent 4B diffusion transformer
- Omni-RoPE position encoding: Multi-image spatial positioning and identity distinction
- Parameter decoupling: Keeps text autoregressive generation from degrading image quality
- In-image text: Generates legible text content inside the generated image
OmniGen2 Model Download
Since this article involves different workflows, the corresponding model files and installation locations are as follows. The download information for model files is also included in the corresponding workflows: Diffusion Models VAE Text Encoders File save location:ComfyUI OmniGen2 Text-to-Image Workflow
OmniGen2: Text to Image
Generate high-quality images from text prompts using OmniGen2’s unified 7B multimodal model with dual-path architecture.
Run on Comfy Cloud
Open and run this workflow directly in Comfy Cloud
Download Workflow
Download JSON or search “OmniGen2” in Template Library
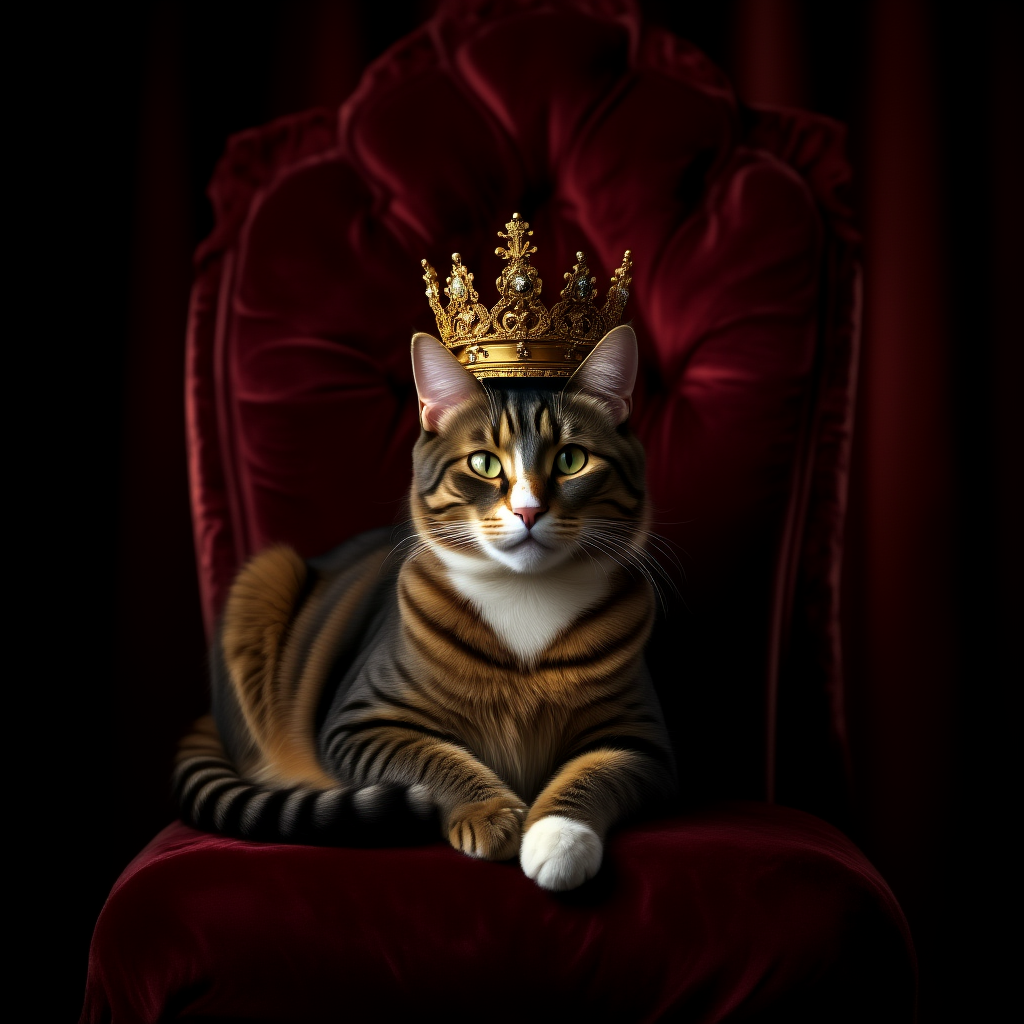
1. Download Workflow File
2. Complete Workflow Step by Step
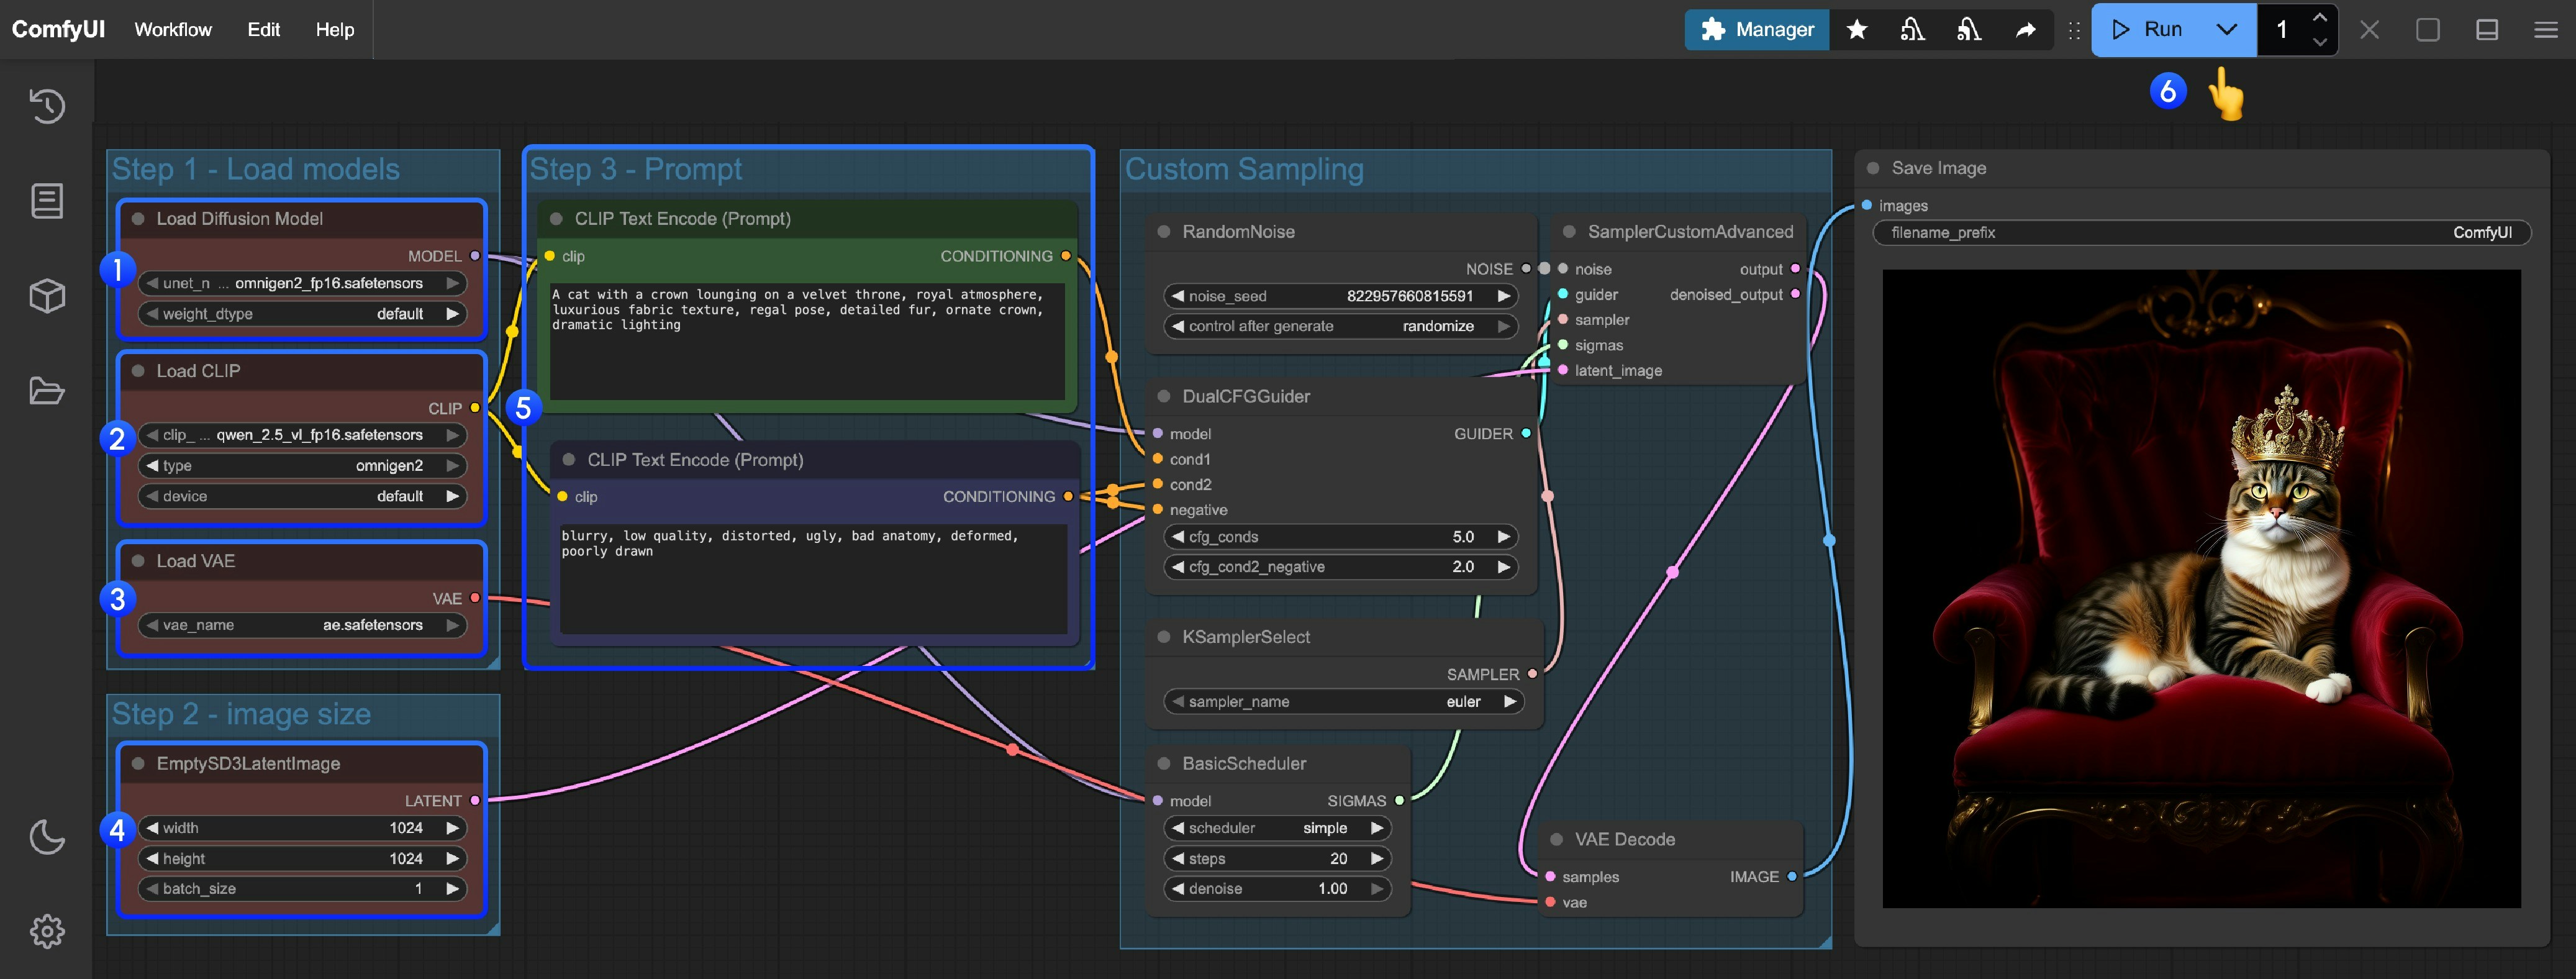
- Load Main Model: Ensure the
Load Diffusion Modelnode loadsomnigen2_fp16.safetensors - Load Text Encoder: Ensure the
Load CLIPnode loadsqwen_2.5_vl_fp16.safetensors - Load VAE: Ensure the
Load VAEnode loadsae.safetensors - Set Image Dimensions: Set the generated image dimensions in the
EmptySD3LatentImagenode (recommended 1024x1024) - Input Prompts:
- Input positive prompts in the first
CLipTextEncodenode (content you want to appear in the image) - Input negative prompts in the second
CLipTextEncodenode (content you don’t want to appear in the image)
- Input positive prompts in the first
- Start Generation: Click the
Queue Promptbutton, or use the shortcutCtrl(cmd) + Enterto execute text-to-image generation - View Results: After generation is complete, the corresponding images will be automatically saved to the
ComfyUI/output/directory, and you can also preview them in theSaveImagenode
ComfyUI OmniGen2 Image Editing Workflow
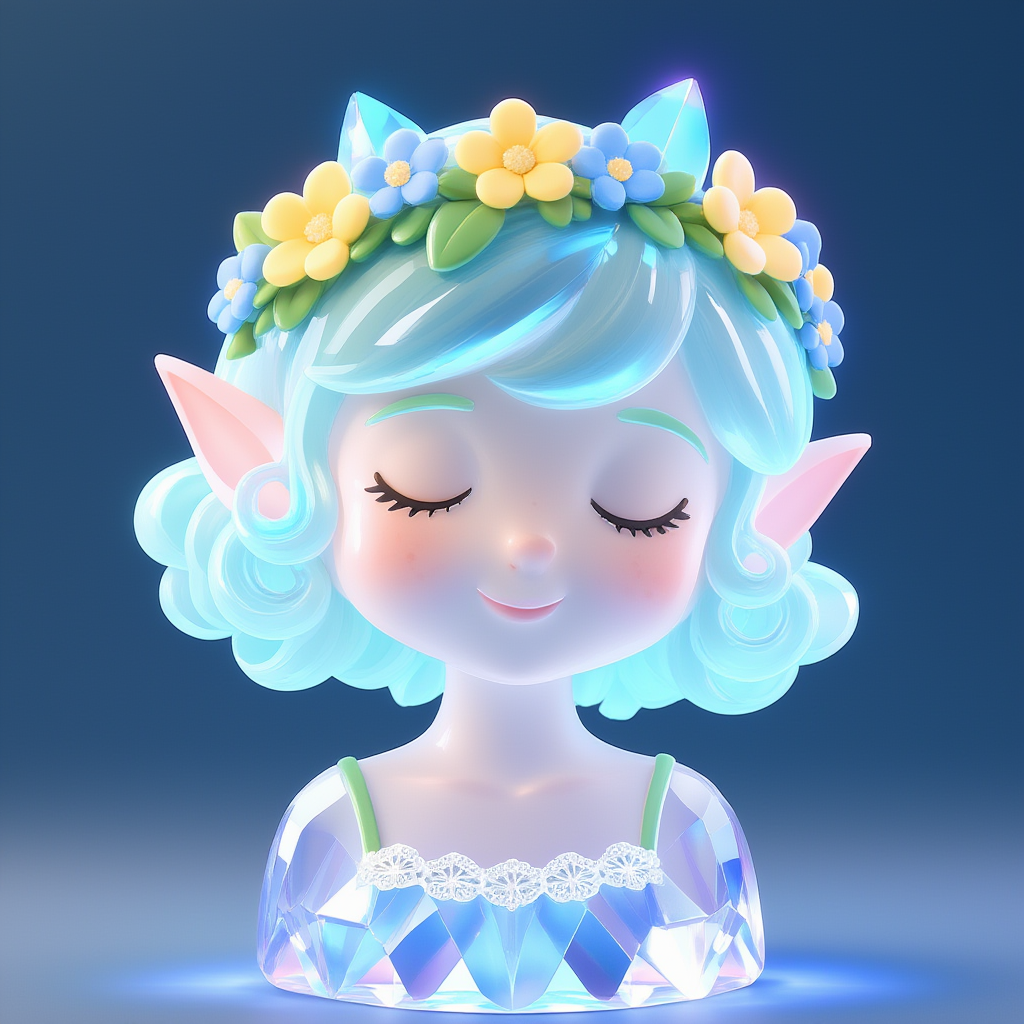
OmniGen2 has rich image editing capabilities and supports adding text to images.OmniGen2 Image Edit
Edit images with natural language instructions using OmniGen2’s advanced image editing capabilities and text rendering support.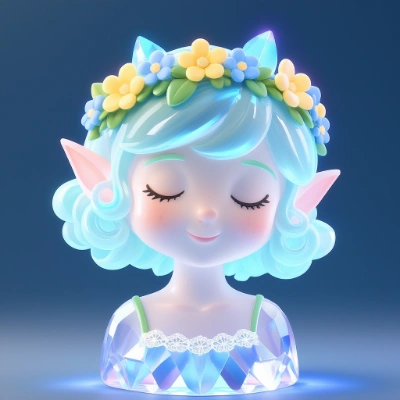
Run on Comfy Cloud
Open and run this workflow directly in Comfy Cloud
Download Workflow
Download JSON or search “OmniGen2 Image Edit” in Template Library
LoadImage node:
image_omnigen2_image_edit_input_image.png
LoadImage node 16 · image_omnigen2_image_edit_input_image.png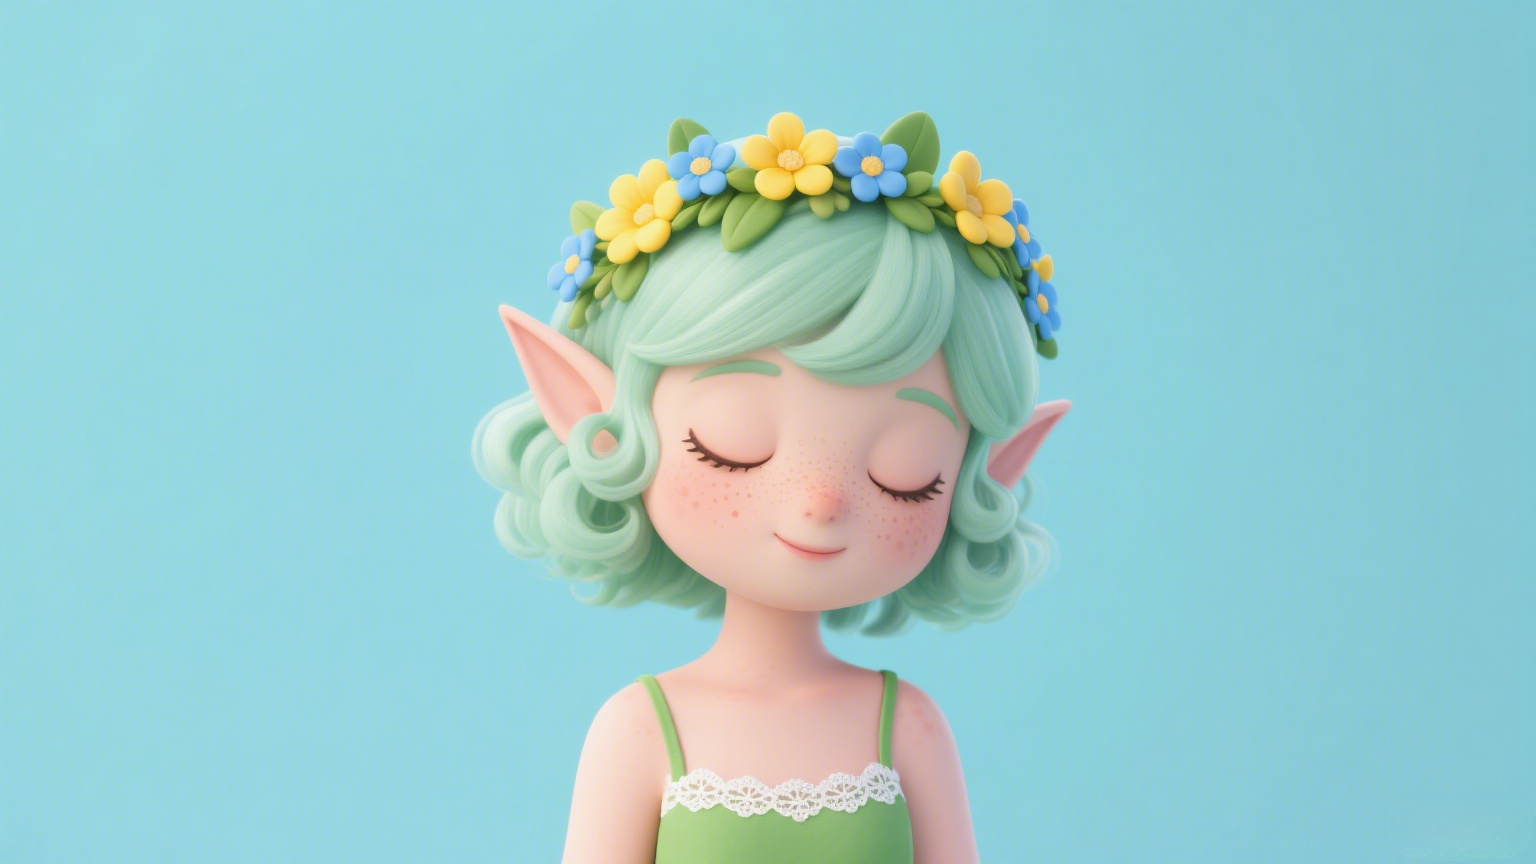
1. Download Workflow File
2. Complete Workflow Step by Step
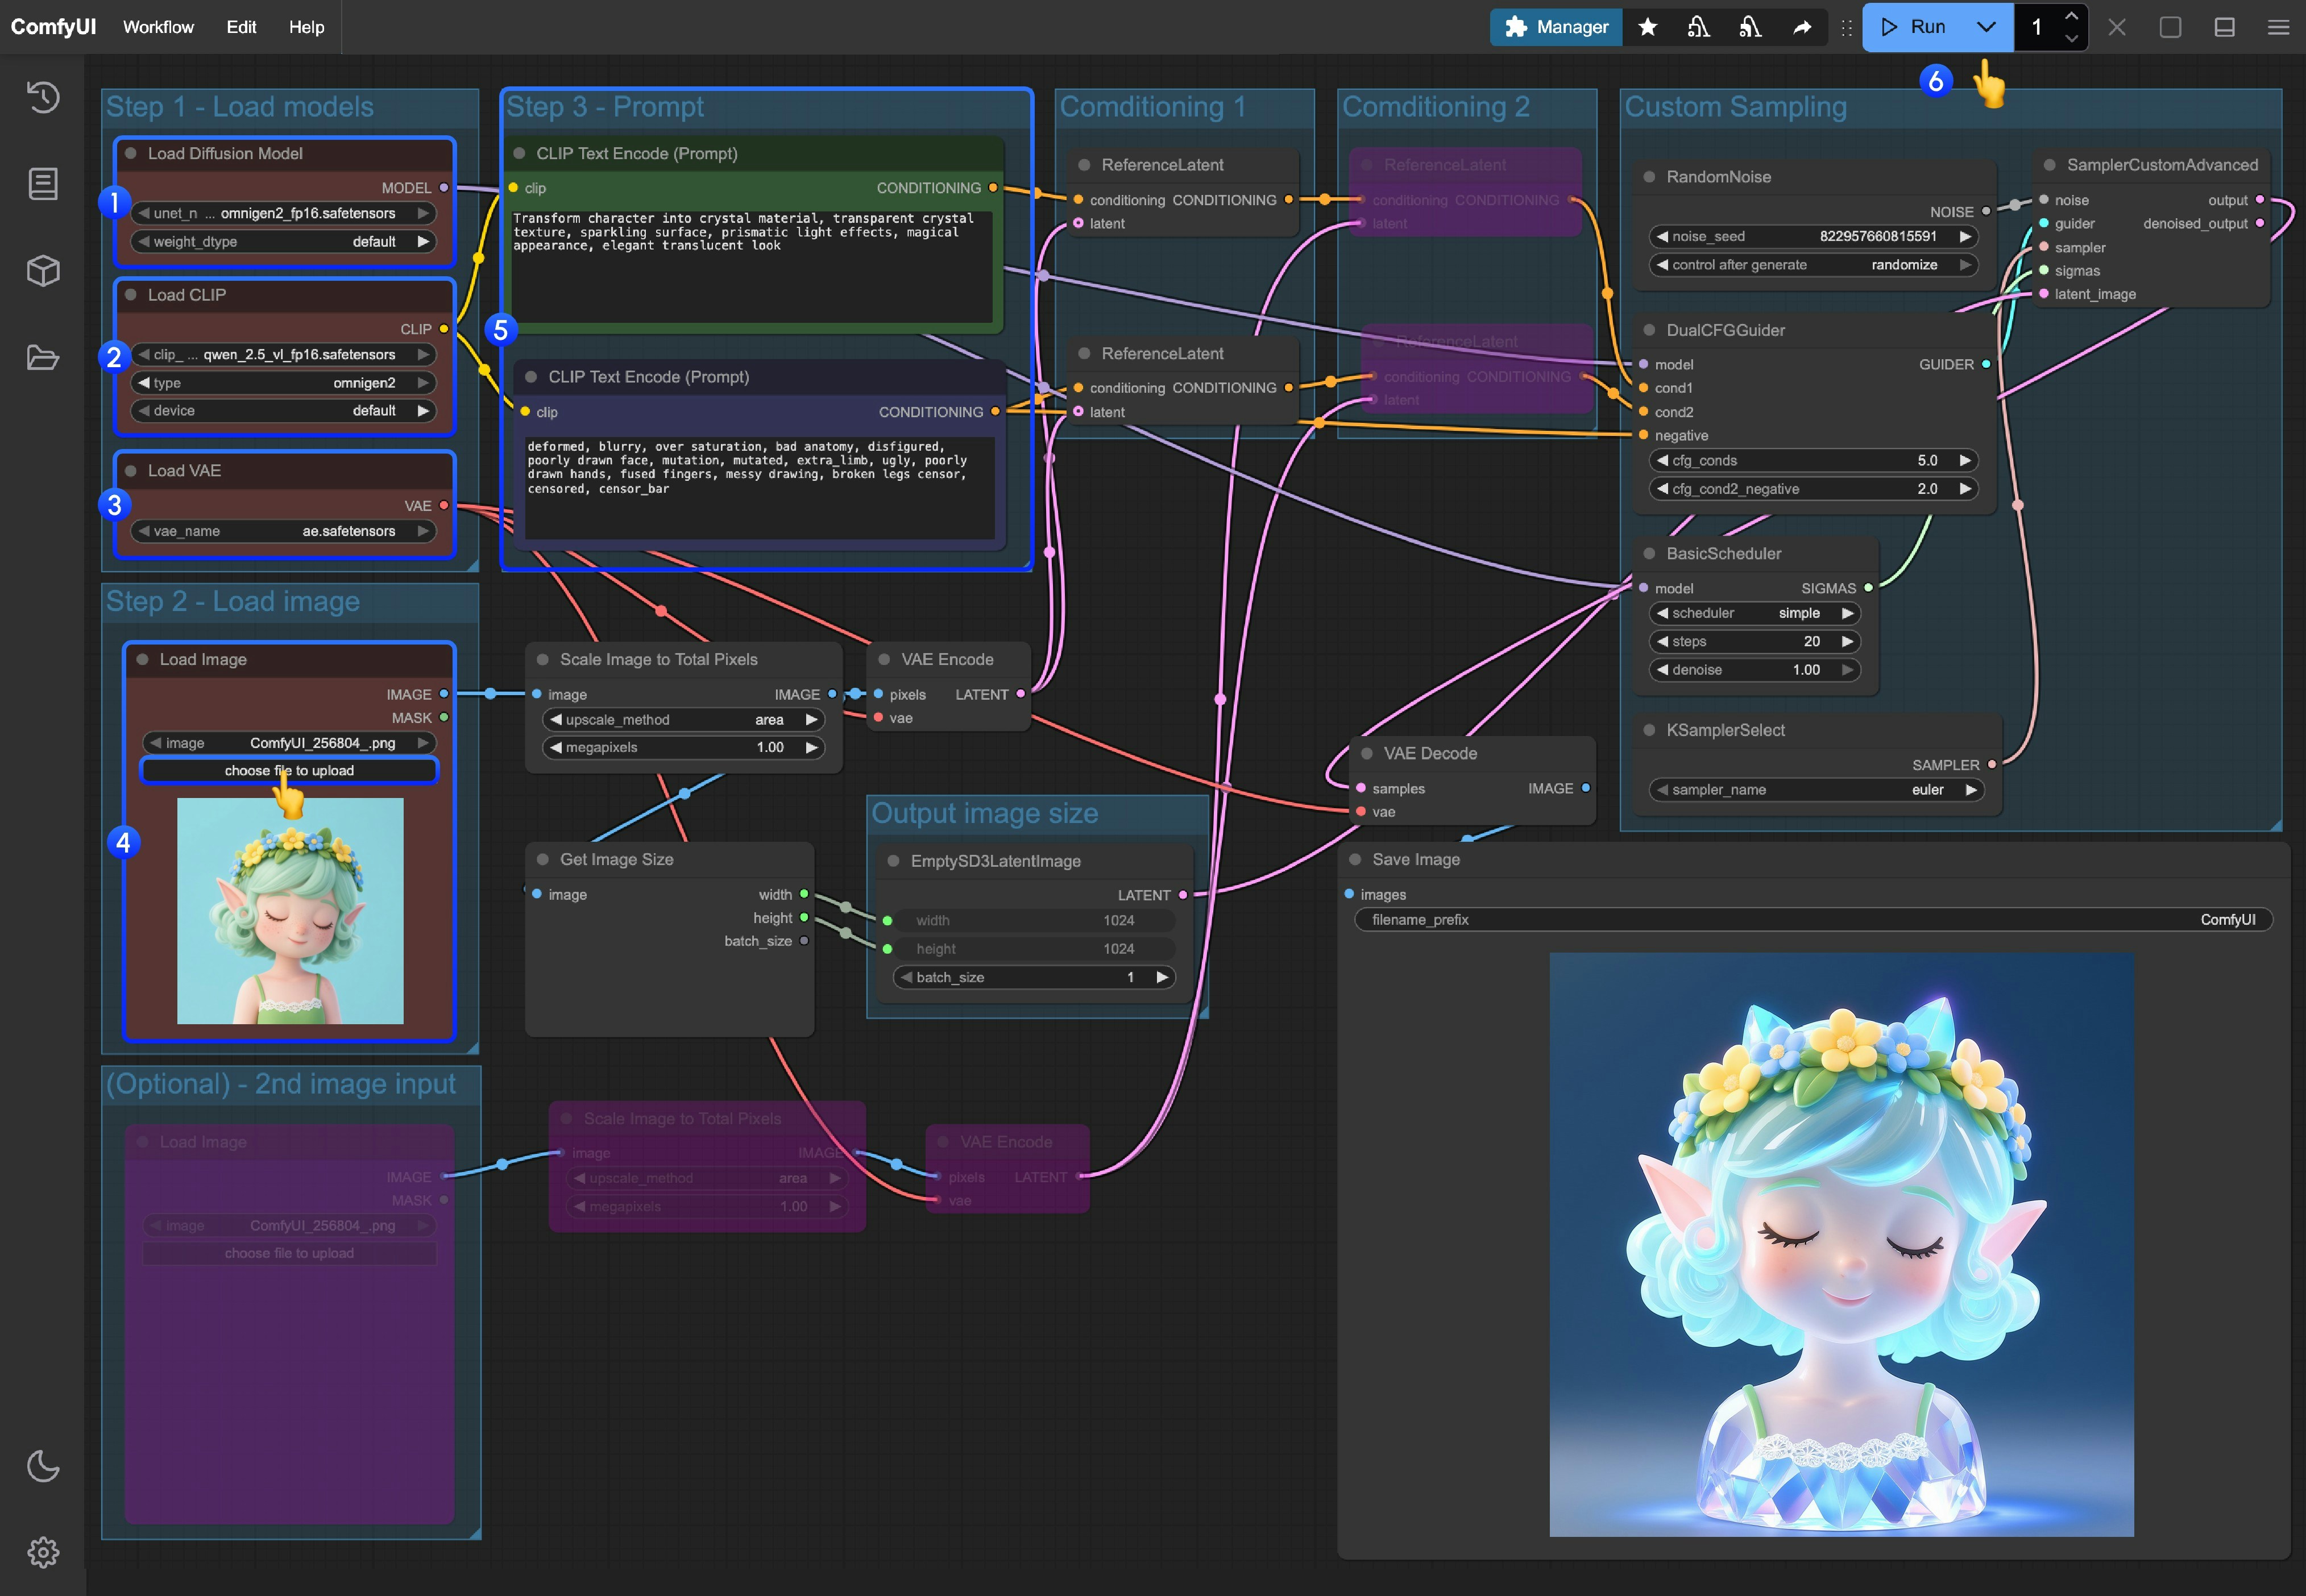
- Load Main Model: Ensure the
Load Diffusion Modelnode loadsomnigen2_fp16.safetensors - Load Text Encoder: Ensure the
Load CLIPnode loadsqwen_2.5_vl_fp16.safetensors - Load VAE: Ensure the
Load VAEnode loadsae.safetensors - Upload Image: Upload the provided image in the
Load Imagenode - Input Prompts:
- Input positive prompts in the first
CLipTextEncodenode (content you want to appear in the image) - Input negative prompts in the second
CLipTextEncodenode (content you don’t want to appear in the image)
- Input positive prompts in the first
- Start Generation: Click the
Queue Promptbutton, or use the shortcutCtrl(cmd) + Enterto execute text-to-image generation - View Results: After generation is complete, the corresponding images will be automatically saved to the
ComfyUI/output/directory, and you can also preview them in theSaveImagenode
3. Additional Workflow Instructions
- If you want to enable the second image input, you can use the shortcut Ctrl + B to enable the corresponding node inputs for nodes that are in pink/purple state in the workflow
- If you want to customize dimensions, you can delete the
Get image sizenode linked to theEmptySD3LatentImagenode and input custom dimensions