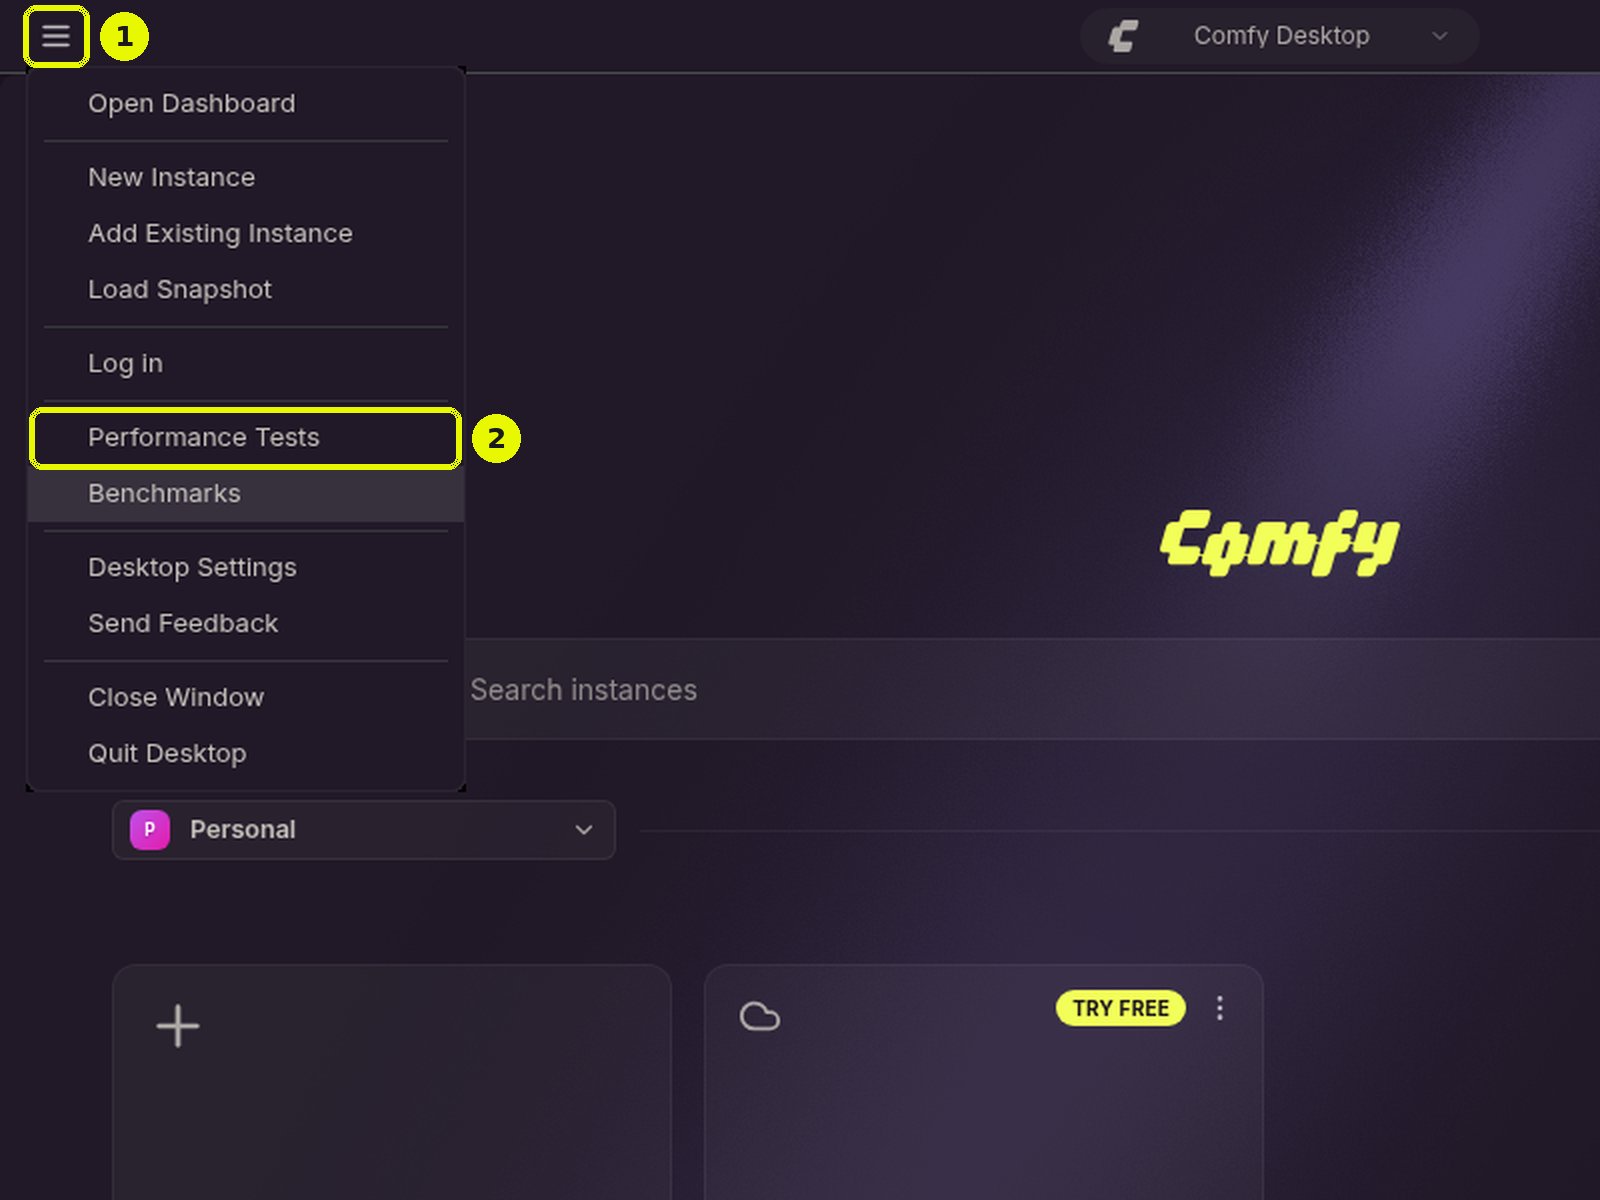
Performance Tests runs a real workflow on a real instance, so a test takes roughly as long as the workflow itself multiplied by the number of runs. Workflows you import have to be exported in API format first. The example workflows that ship with Comfy Desktop are already in that format.
Running a Performance Test
The panel is laid out as three numbered steps side by side. They stack vertically on narrow windows.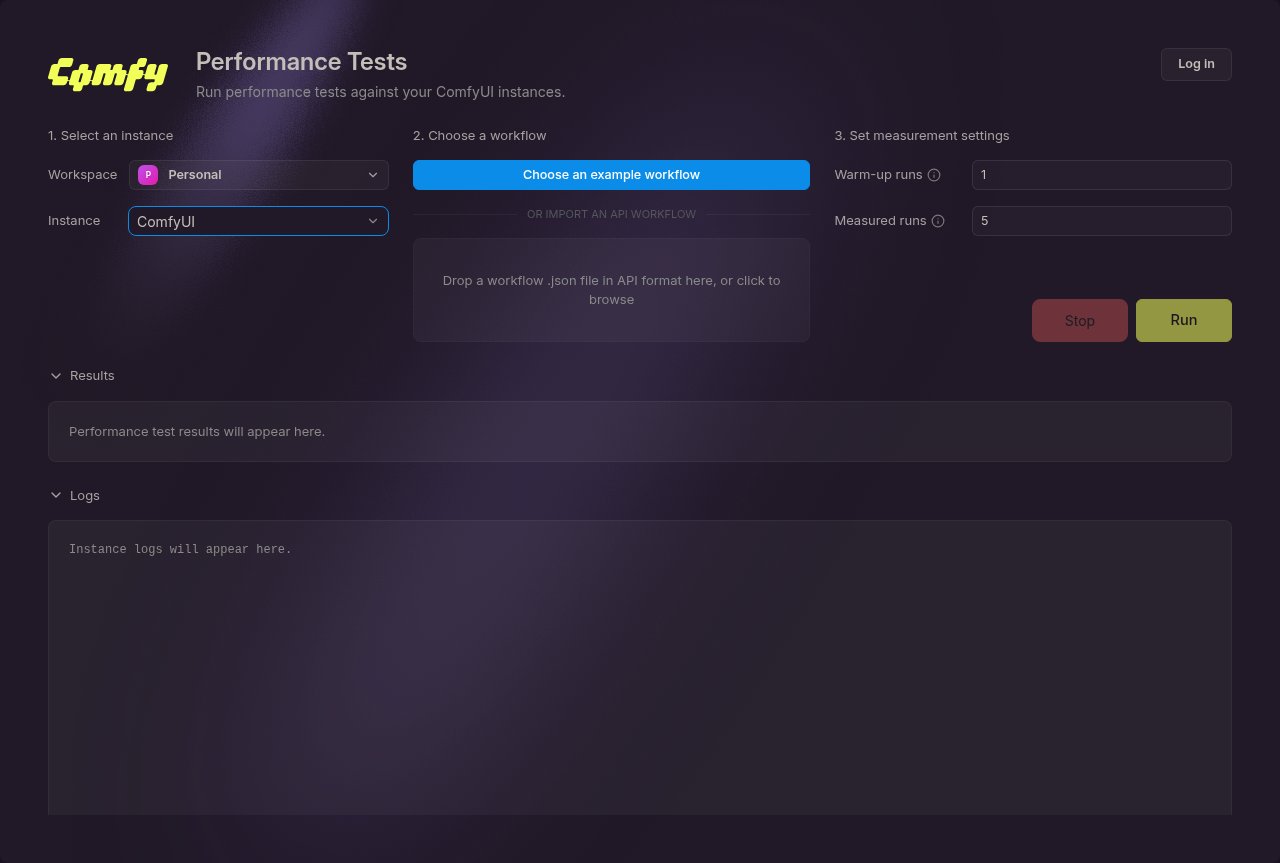
1. Select an instance
Choose the Workspace and the Instance to test. The instance and its hardware are recorded with the results, which is what makes later comparisons meaningful: runs from different GPUs stay distinguishable. When you start a test, Comfy Desktop stops that instance’s previous performance test session if one is still running, then launches the instance in a console session. Comfy Desktop refuses to start a test while any other local ComfyUI is running, still starting, or stopping, and names the instances in the way. Stop them, or wait for them to finish starting or stopping, then run the test again. Comfy Cloud and remote instances run elsewhere and never block a test. Other work that keeps the GPU busy, such as a game or a video export, still affects the numbers, so stop it before you run a test.2. Choose a workflow
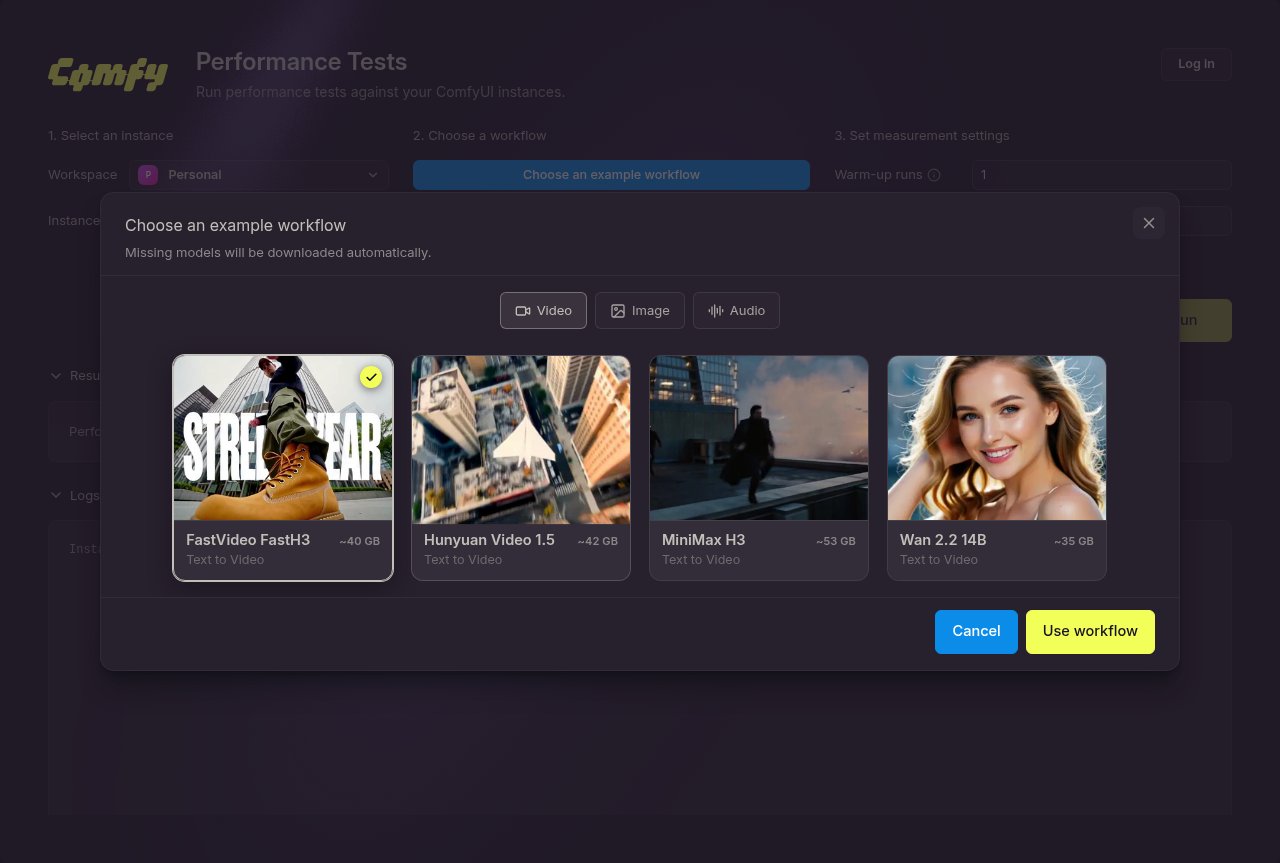
You can pick an example workflow that ships with Comfy Desktop, or bring your own. Example workflows are ready to run, and their models are downloaded for you. Click Choose an example workflow to open the picker. It groups the examples into modality tabs (Video, Image, 3D, and Audio; only modalities that have examples get a tab), and each card shows the example’s name, task, and how much its models download. Click Use workflow to select one. Comfy Desktop then downloads any models the workflow is still missing, and the drop zone shows the download progress until it finishes. To pick an example, the instance has to be fully installed and you have to be online; if the models would not fit in the free disk space, the picker blocks the selection. Example workflows are tied to an instance: switching to another instance drops the example prepared for the first one, unless that example’s session already recorded results. Your own workflow has to be exported in API format. Drop the.json file onto the drop zone, or click the zone to browse for one.
3. Set measurement settings
Every run advances the workflow’s numeric seed inputs by one, so the measured runs do not repeat an identical cached result.
Once the three steps are set, click Run to start the test. The Stop button next to it cancels a test that is in progress.
Read the results
While the test runs, the panel shows how many runs have finished and the instance logs. When every run finishes, the instance is stopped and the results appear:- Fastest run, Slowest run, Average run, and Median run, in seconds
- Measured runs and Failed runs: how many runs produced a duration and how many did not
- Run duration aggregates: a bar chart comparing the four aggregates (fastest, slowest, average, and median)
- System information: compute device, VRAM, RAM, PyTorch version, xFormers version, CPU, CPU cores, operating system, and architecture
Comparing Runs with Benchmarks
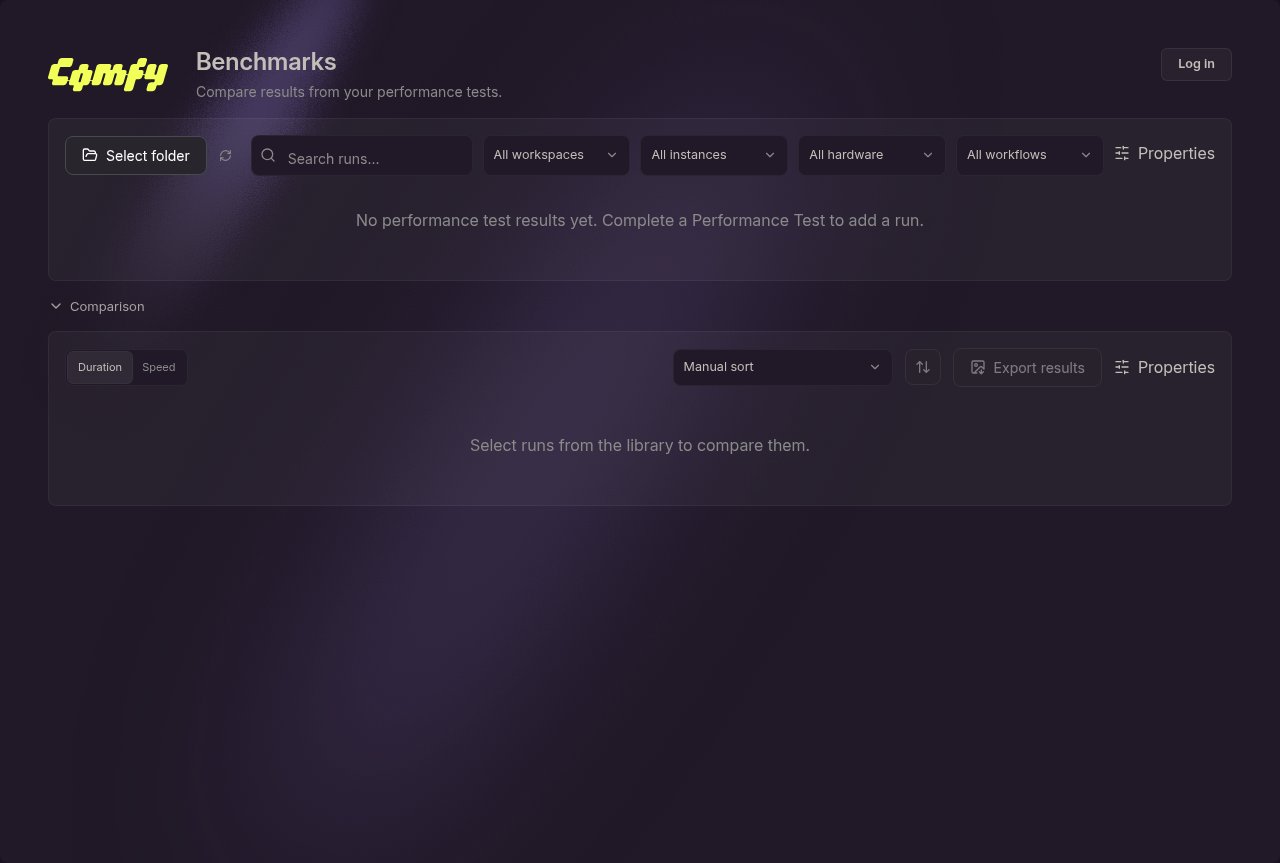
Benchmarks reads the results that Performance Tests saved, so it has nothing to show until at least one test has finished.Runs library
The Runs library lists every saved run in the results folder, newest first. Its toolbar gives you:- Select folder: point the panel at a different results folder, for example a folder on a shared drive. The default is the folder Performance Tests writes to, see Where results are stored.
- Refresh sessions: reload the folder after a test finished elsewhere.
- Search runs: filter the list by text.
- Dropdown filters for workspace, instance, hardware, and workflow.
- Properties: choose which columns the library shows (session, date and time, workflow, instance, workspace, run count, GPU and hardware).
Compare runs
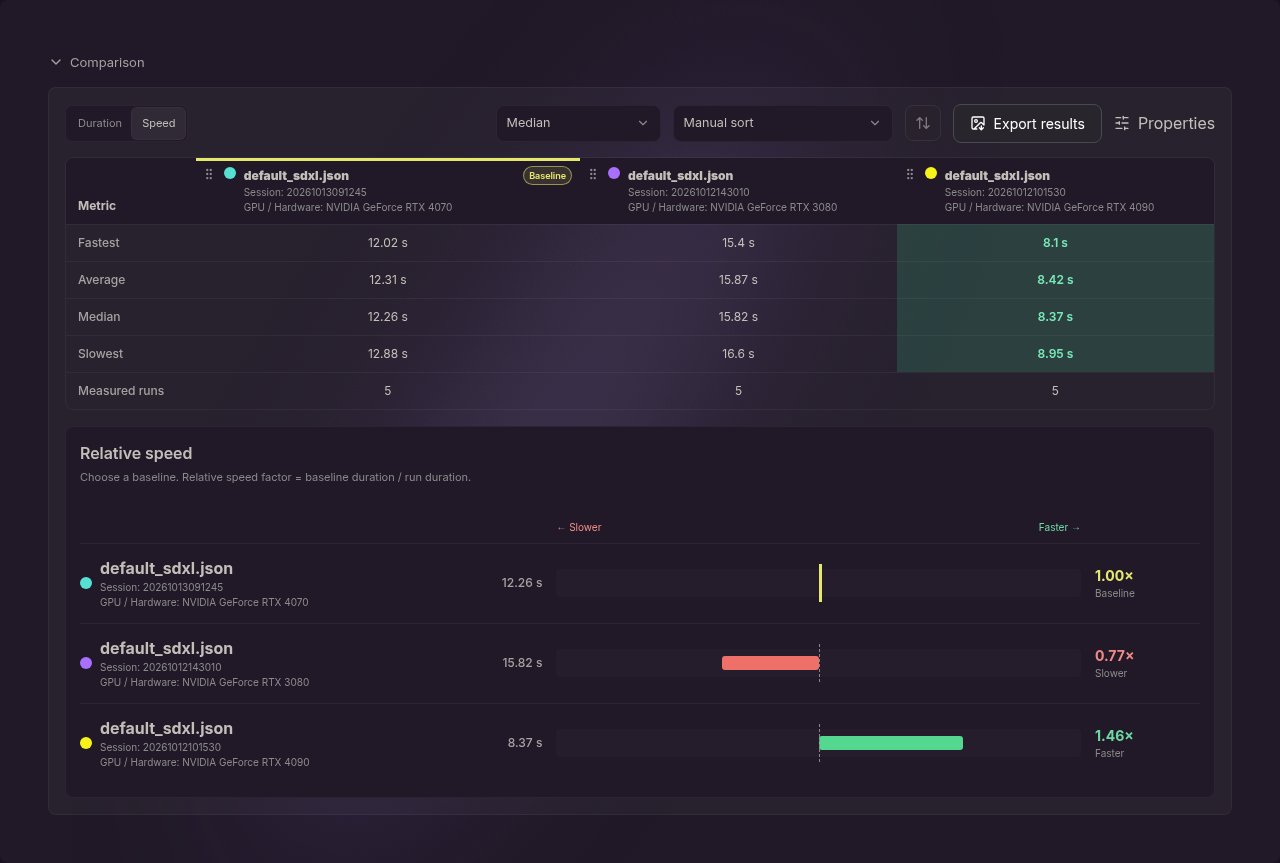
Select two or more runs with the checkboxes, or use Select all visible runs. The three newest runs are selected for you when the library loads. A selection opens the Comparison section below the library. Comparison puts one column per selected run next to a set of metric rows: fastest, average, median, and slowest duration, plus the measured run count. One run is the baseline. By default it is the first column shown. In the Speed view, click a column heading to make that run the baseline instead.Relative speed
The comparison has two views, Duration and Speed, which you switch between in the comparison toolbar. Relative speed belongs to the Speed view, and the baseline is chosen there too. Relative speed is the baseline duration divided by a run’s duration:- 1.00× means the run is the same speed as the baseline
- A factor above 1.00× means the run is faster than the baseline
- A factor below 1.00× means the run is slower than the baseline
Sort and export
- Sort comparison orders the columns by relative speed. Manual sort lets you drag columns into your own order, or press Alt+Left / Alt+Right on a focused column.
- Export results saves the whole comparison as a PNG image, the quickest way to attach a result to an issue or a chat message.
Manage sessions
Each test is stored as a session. From the library you can rename a session (Edit session) or delete one (Delete). Deleting removes every file recorded for that session.Where results are stored
Performance Tests creates a session folder when you add a workflow to the panel, named with that moment’s timestamp (YYYYMMDDHHMMSS):
Each session folder contains:
- the workflow file the panel used
jobs.json: the raw job response from the instanceresults.json: the summary the Benchmarks panel readslogs.txt: the instance console output from the run
results.json from every session folder it finds, copying session folders into the folder Benchmarks points at is enough to compare results from another machine.
Running the same imported workflow again writes into the same session folder and overwrites the results already stored there. To keep a result for comparison, add the workflow to the panel again before the next test.
Requirements
- A standalone, tracked, or remote instance that Comfy Desktop can launch. The test needs a working ComfyUI instance, so it cannot run against a Cloud instance.
- A workflow the instance can execute, including any models and custom nodes it needs. A workflow you import has to be in API format; the example workflows already are, and Comfy Desktop downloads their models. If the instance rejects the workflow, the test stops and the error appears in the logs. Runs the instance accepts but that fail during execution are counted as failed runs and left out of the duration statistics.